Find what your buyers say when you are not in the room.
Research public conversations across Reddit, YouTube, forums and industry sources. Every finding comes with quotes, links and the counts behind it. Pricing starts at $0.60 per topic or website.
Built for SaaS founders, CEOs and teams making decisions about positioning, content, pricing and product. Use it to find repeated questions, objections and the words buyers actually use. It reflects the people who discuss the problem publicly; it is not a statistically representative market study.
Register with your work email and bring one audience plus the business question you need answered. We will follow up personally.
From $0.60 per topic or website · three research depths
Price the audience questions you need answered.
Choose topics or websites, enter the batch size and select the research depth. The estimate uses the published per-unit rate, so the total changes only when your volume or tier changes.
List-price estimate only. Lite, Standard and Pro are levels of research depth, not seat plans. The rate card does not publish numeric source-count or deliverable limits, so none are invented here; the brief determines the appropriate tier before the research runs.
Guessing at your buyers is not free. It is just billed as something else.
Nobody puts a line called “we guessed” in the budget, so the cost turns up somewhere else. It turns up as engineering time spent on a feature that came out of one loud call and was never asked for again. It turns up as paid spend bidding on the words your team uses, while the audience searches for the same problem under a name nobody in the building has typed.
It turns up as a landing page that argues hard against the objection you already knew about and stays silent on the one that actually stops the purchase — the cost a year in, the migration, the thing your competitor's users complain about in public every week. And it turns up as a churn reason you only hear at the cancellation, when the same worry was being typed out in the open long before anyone left.
None of it arrives as a research invoice. It arrives as a roadmap, an ad budget and a landing page all pointing in a slightly wrong direction, and then as the work of turning them round.
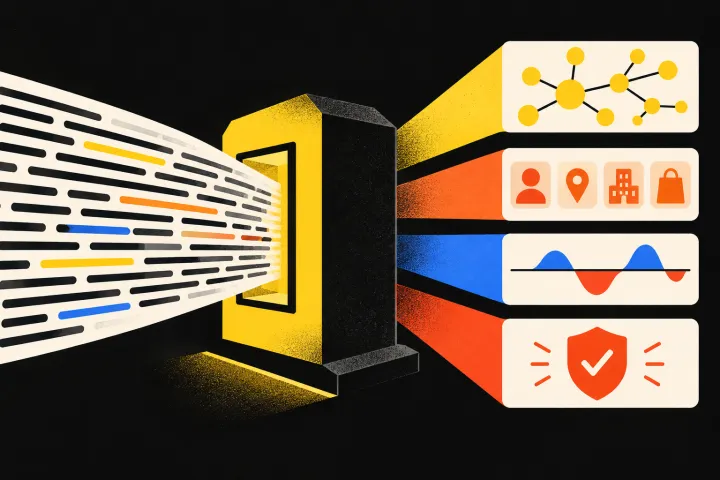
One audience, one question, one dataset — and nine different things you can act on, from the words you should be bidding on to the question nobody in the discussion has answered.
Keep the conversations you can have. Send us the ones you will never be in.
This does not replace talking to your customers, and it does not read your CRM, your support desk or your product analytics. Your interviews, calls and churn exports explain the people who already found you. Audience Intelligence covers the part of your market that discusses the problem publicly and has never spoken to you, then returns the questions and language your team was not in the room to hear.
Keep doing this yourselves
- Customer interviews. No open thread tells you why this particular buyer signed, and follow-up questions only work live.
- Sales calls and lost-deal reviews. Your team already hears the objections that kill deals — what it cannot hear is how many people repeat the same objection and never book a call.
- Your own churn data and product analytics. It is yours, it is complete for your users, and nothing external substitutes for it.
- Anything private: NDAs, closed communities, your support inbox. We read what is open, and only what is open.
- The decision itself — what to build, what to charge, what to say. This is evidence for that meeting, not a replacement for it.
Send to OmevAI
- The exact words people use for the problem in public, which are rarely the words on your homepage.
- The questions people keep asking about a product like yours, including the ones your FAQ has never answered.
- The objections people raise most often when weighing a product like yours: what it costs a year in, how long setup really takes, what happens the first time it goes wrong.
- The gap between what an influencer praises and what the comments underneath are asking about instead.
- What the audience keeps asking and nobody in the discussion — you included — has answered.
- Whether a question is getting louder, checked again in the next period rather than remembered.
What comes back.
One thing to send, and the separate decisions it can settle once it comes back.
The words the discussing part of your audience uses for the problem
Goes straight into your landing page copy, your ad terms and what you try to rank for. If you write in your product's vocabulary while they describe the problem in theirs, you are paying for clicks and pages that never match the words in their head.
The questions they ask before they buy
Shapes page structure, FAQs, onboarding and what your team says when the objection comes up. Every question your site does not answer gets answered by a competitor, a forum thread, or nobody — and guessing which questions matter is how a page ends up long and still unconvincing.
What your pricing and product pages have to show
Becomes the spec for the page: the specifics people say they look for and cannot find. Rebuilding a pricing page on an internal opinion is an expensive guess, because you find out it was wrong long after the traffic has been through it.
The comparisons they run before choosing
Sets what your comparison pages argue and what sales says when a competitor's name comes up. Buyers rarely compare on the axes you would choose, and a comparison page built on the wrong ones argues a case nobody was making.
Where the influencer and the audience are talking about different things
The post praises the design; the comments underneath are asking about the noise. That gap is where a sponsored placement quietly fails, and it is the cheapest thing on this list to act on — an edit to the brief before the money is spent, rather than a post-mortem after it.
What you never mention and they keep raising
Sometimes it changes what you publish next. More often it changes what you ship next. You cannot see your own silence from inside the company, so guessing here means paying to produce more of what you already cover while the thing people actually ask about stays unaddressed.
What buyers say has to be true before they will pay
Arms sales materials, proposals and the argument the pricing page has to win. A missed expectation does not lose you an argument, it loses the deal before you are in the room to have one.
A brief a writer can work from
The same evidence arranged as instructions rather than findings: what the piece has to answer, in whose words, and which questions it is not allowed to leave open. It is the difference between handing someone a research document and handing them a job, and it is the reason the work does not end up in a folder nobody opens.
Which of those questions are being asked more than they were
Only visible by running the same brief over a later period and comparing the two, which is a decision you take rather than a subscription that runs. A question getting louder in public is worth knowing about before it reaches a renewal call — whether it will reach one is not something this data can tell you.
What it costs.
Audience Intelligence is priced per topic or website researched: Lite is $0.60, Standard is $0.70 and Pro is $0.75. Lite fits a focused question, Standard a broader cross-source brief, and Pro the most involved research with competing views or a deeper evidence trail. The rate card does not publish numeric source-count or deliverable limits, so the brief determines the tier before the work runs.
Lite
$0.60 per topic or website
A focused question about one clearly defined audience, topic or site.
Standard
$0.70 per topic or website
A broader brief that needs evidence compared across more of the public conversation.
Pro
$0.75 per topic or website
The most involved questions, where competing views and a deeper evidence trail matter.
List prices, checked 21 September 2026 · per topic or website researched
What this looks like in practice.
Rewriting the pricing page
You sell cold-email automation to sales teams, and trials start but stall at the pricing page. Nobody internally agrees on whether the blocker is the price, deliverability worries, or how much setup work people think it takes.
The questions that audience actually asks before buying — how to avoid landing in spam, how to personalise a mass campaign from their own records, how long the first campaign takes to set up, what people say they will pay for — each carried with quotes, links and counts, for the audience and period you chose rather than the market as a whole.
Choosing next quarter's roadmap
Your roadmap is assembled from the requests of your ten loudest customers plus whatever sales heard last week. You want to know what the active discussion in your category treats as table stakes, and what it treats as a reason to switch.
Two separate pictures — the expectations that come up again and again, and the contested ones where the audience genuinely splits — with the disagreement kept apart instead of averaged into one tidy recommendation, and a route back to the source behind every claim you would act on, for the audience, language and period you set rather than your category as a whole.
Opening a second market
You are about to launch in Germany and the plan is to translate the English site. You do not know whether German-speaking buyers raise the same objections, or even use the same words for the problem.
The vocabulary, questions and objections from the audience, language, geography and period you name, so you can see where a translated page would answer questions nobody there is asking and where it would stay silent on the ones they are. One caution: quiet is not the same as no demand. A thin discussion tells you the discussing audience is small there, not that the market is.
How much has to change.
You set a brief, not a search term. Five things you already know without asking anyone: the audience you sell to, the geography, the language, the period the evidence has to come from, and the one business question you want answered — why they buy, why they stall, what they weigh you against. “What stops a 40-person sales team from switching billing tools” is a brief. “The billing software market” is not. The narrower the audience and the tighter the window, the more the phrases that come back sound like the people who actually pay you.
One piece of research, nine ways to use it: the phrases your buyers type; the questions they keep asking; the things your landing page is expected to answer; the comparisons they make unprompted; a brief a writer can work from; the subjects your brand is silent about; the gap between what the influencer said and what the comments underneath actually asked; what buyers say has to be true before they commit; and which of those questions are being asked more than they were last time. Every conclusion carries its quotes, its links and the counts behind it, so any line of it can be argued with. Where the audience splits, both positions are kept and shown separately instead of averaged into one tidy sentence. Nothing has to be built on your side to get the first one. An engineer is involved only when you decide to run this on a repeat, and the docs below are for them.
Read the API docs →What we can actually prove.
Every claim below is either arithmetic on published rate cards or a fact you can check. We do not publish quality benchmarks we ran on ourselves — we run yours instead.
Every conclusion arrives with its quotes, its links and a count of the people and threads behind it.
How this is supported
This is a property of what comes back, not a score we awarded ourselves. Take any conclusion and the evidence is either under it or it is not. Follow it and you are reading what a person actually wrote, in the thread they wrote it in. A conclusion that turns up without that has failed, and the pilot is where you say so. We publish no accuracy percentage, because there is no honest way to compute one over open discussion, and an invented figure is worth less to you than a link you can click.
Conflicting opinions are kept apart, not averaged into one view.
How this is supported
Where the audience splits, you get both positions with their own quotes and their own counts, rather than a summary sentence that hides the split. Test it on something you already know divides your market — pricing model, self-serve against sales-led, whatever your own buyers argue about — and look for the disagreement in what comes back. If it has been smoothed into a single view, the work is wrong and you have a concrete thing to point at.
The path back to the source is stored for every significant claim.
How this is supported
This is where research documents usually fail: a line gets questioned weeks later and somebody has to go hunting for the link again. Checkable at any time, on anything we hand you — take a line out of a deliverable, follow it back, and either the source opens or the claim does not stand.
This is the active, discussing part of your audience over the period you chose. It is not the market.
How this is supported
People who post, comment and argue in public are a self-selected slice of any market, and never a random one. What comes back describes them, inside the geography, language and timeframe you set, and nothing beyond that. It is not statistically representative, it does not replace a survey, and it does not replace a sales call. We would rather write that on the page than have you discover it in the pilot. What it is good for is language, questions and objections — what people say in their own words when you are not in the room.
Questions before you send us anything.
How is this different from asking ChatGPT to summarise the forums?
A summary comes back fluent and unverifiable. You cannot tell which part came from three people and which from three hundred, and you cannot find the thread it came from. Here every conclusion comes with its evidence attached — quotes, links and the counts behind them — and the route back to the source is kept, so a claim you doubt gets followed back instead of argued about. It also reads more than one kind of place: the discussions under the influencers with the most active comment sections in your niche, plus industry publications, forums and other open debate. And it reads the audience reaction, not the influencer's own opinion.
How do I know it is not made up?
You check it, and checking is mechanical rather than a matter of trust. Pick the conclusion you like least, open the source, read what was actually written. During the pilot we agree what counts as evidence before anything is collected — which sources are in scope, and how many independent people have to say a thing before it counts as a finding. We propose that threshold and you sign it off or move it, so the standard is set in advance rather than defended afterwards. We publish no accuracy or coverage figure. There is no honest way to compute one over open discussion.
What if the audience disagrees with itself?
Then you see the disagreement. Conflicting positions are stored and shown separately, each with its own quotes and its own counts, and never merged into an average. That is usually the most useful part of the work: the split in what your buyers want is where your pricing page and your onboarding are quietly losing people. Anything that resolves the conflict for you has destroyed the finding.
Does this replace talking to customers?
No, and do not buy it on that basis. This reads the part of your audience that discusses things in public, in the period you chose. Those people select themselves, they are not a sample, and they are not the whole market. What they give you is language and objections at a volume no interview schedule reaches: the exact phrases, the questions asked over and over, the thing your category never addresses. Interviews tell you what someone will say to your face. This tells you what they say when you are not there. Do both.
How do Lite, Standard and Pro differ?
They are research-depth tiers, not seat plans. Lite is the lowest-cost route for one focused audience question. Standard is for a broader brief that needs evidence compared across more of the public conversation. Pro is for the most involved questions, where competing views or a deeper evidence trail matter. The public rate card does not promise fixed source counts or report lengths for any tier, so those limits are not invented here.
What does it cost?
Lite is $0.60, Standard is $0.70 and Pro is $0.75 per topic or website researched. Multiply the number of topics or websites by the selected tier. The calculator above does that arithmetic for you.
How do I start?
Register at the dashboard, as with everything else here — every registration reaches a person. Bring one audience and one business question. We agree what counts as evidence, gather it, and build two different deliverables on it, so what you are judging is the evidence rather than a document. Nobody technical is needed for any of that. You need an engineer only when you decide to run this yourself, and they work from the docs linked above.
Other use cases
Price the audience questions you need answered.
Choose the number of topics or websites and the research depth. Lite starts at $0.60 per unit. Register with your work email and we will follow up personally about the first brief.
From $0.60 per topic or website · three research depths · One audience, one question