LiteLLM
What is LiteLLM?
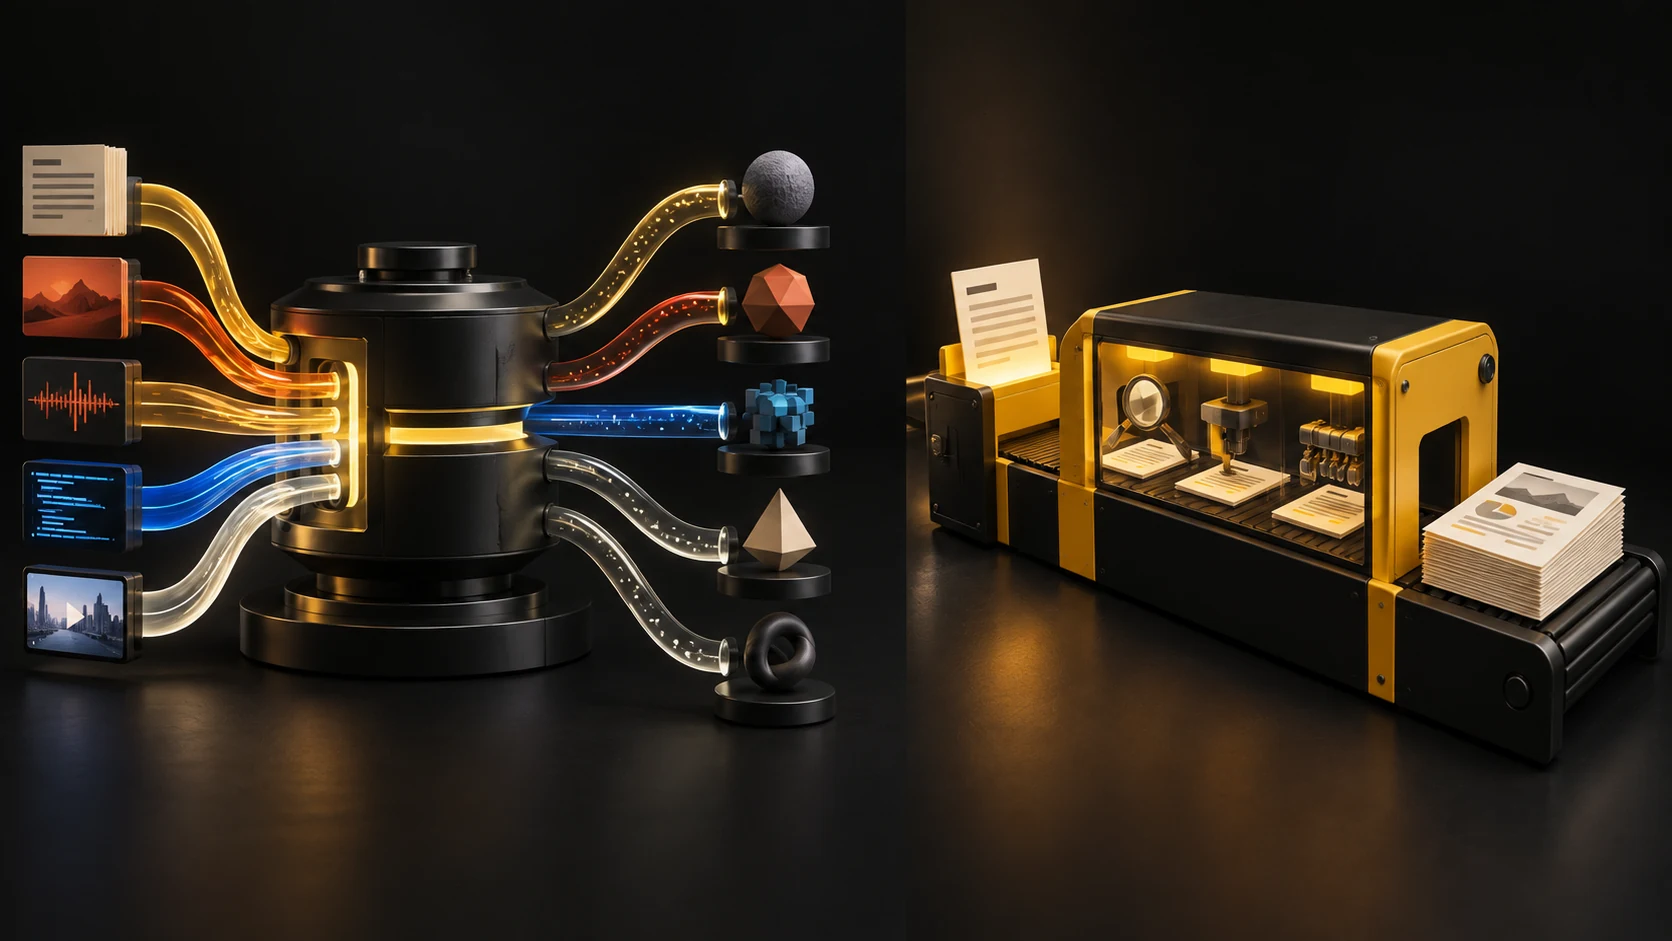
Its SDK and proxy standardise model calls and can add authentication, logging, budgets, load balancing, retries and fallbacks. Your team chooses the providers and operates the setup.
LiteLLM alternative · comparison updated September 2026
If you are looking for a LiteLLM alternative, start with the job you need done. LiteLLM gives your team one gateway across many providers. Omev runs selected business workloads on its own models. The products overlap at the API, but they solve different operational problems.
$5 free credit · 10 days · no card

By Di Reshtei, Co-founder of OmevAI · X
LiteLLM sources checked
Quick answer
Yes—for selected workloads. No—as a drop-in LLM gateway. Choose Omev when you want to move a defined, repeated business task. Choose LiteLLM when your team needs to connect, govern and route many third-party models from one place.
LiteLLM
Its SDK and proxy standardise model calls and can add authentication, logging, budgets, load balancing, retries and fallbacks. Your team chooses the providers and operates the setup.
Omev AI
You bring a real workload and its approval rules. Omev runs that work on its own models, so your team can compare accepted output, review time and total cost.
You need one gateway, many providers, shared access controls and fallbacks your team manages.
You need one repeated workload to keep its client rules, output format and review standard.
You want LiteLLM to remain your model control point while Omev handles a named production workflow.
This is not a model-quality ranking. It compares ownership and product scope using LiteLLM's published documentation and Omev's current offer.
| Decision | Omev AI | LiteLLM |
|---|---|---|
| What you are buying | A direct API for repeatable business tasks, served by Omev's own models. | A gateway and Python SDK that connect your application to many model providers. |
| Model choice | Omev Lite and Pro for text workloads. Omev chooses between its own models for the task you configure. | More than 100 provider integrations through a shared interface. Your team decides which providers and models are available. |
| Who operates it | Omev operates the models and inference service. Your team integrates the selected workload. | Your team self-hosts the open-source gateway or buys an Enterprise deployment and support plan. |
| What routing is for | Applying the right client rules, output format and checks to a known task. | Sending calls across providers and deployments with load balancing, retries and fallbacks you configure. |
| Who defines the workflow | You provide real examples and approval rules; Omev configures the repeatable task around them. | Your team builds and maintains the prompts, provider rules, guardrails and application logic. |
| How the cost works | Published usage rates: $0.15/$1.25 for Lite and $0.625/$5 for Pro per 1M input/output tokens. | The open-source gateway has no licence fee. You still pay model providers, infrastructure and the people who operate the stack. Enterprise is quoted separately. |
| Best fit | A defined, repeated workload whose approved output and margin you can measure. | A platform team that wants one control point across a broad model stack. |
The self-hosted LiteLLM gateway has no licence fee. Omev charges published usage rates that include its model inference. Neither number is a fair comparison until you include the rest of the work your company pays for.
Omev AI
LiteLLM
LiteLLM Enterprise adds governance, security and support on quoted annual pricing. Its official pricing says the quote is based on annual gateway request capacity, deployment architecture and support needs—not token usage.
Decision guide
Choose LiteLLM when your team wants to operate a gateway across many providers. Choose Omev when you want one repeated business job handled for you.
If your requirement is an open-source or self-hosted LiteLLM proxy alternative, Omev is not the direct replacement. If the real goal is to remove one expensive production workflow from that stack, Omev is worth benchmarking.
A practical combined setup
You do not need an all-or-nothing migration. Keep the gateway for broad model access and send one approved, repeatable task to Omev through a separate route.
General model traffic
Provider choice, shared keys, budgets, broad fallbacks and the model-specific work your platform team already manages.
Named production tasks
The content, catalogue, localization or similar workflow with clear client rules, output format and approval criteria.
The goal is not fewer tools. It is clear ownership for every workload.
The current route stays connected until the new one proves itself. Use a small, measurable workload and make the decision from accepted output.
Choose work that repeats and already has a clear owner.
Use briefs and outputs your team has already approved.
Agree the facts, format and review rules before testing.
Keep LiteLLM live while the same sample runs through Omev.
Compare accepted output, review time and total cost.
LiteLLM changes quickly. We checked the official project documentation, pricing page and repository on September 21, 2026. Verify the current offer before making a production decision.
Yes for selected, repeatable business workloads. No as a drop-in replacement for a broad LLM gateway. LiteLLM connects your application to many model providers. Omev runs defined work on its own models. Choose Omev only for the jobs it can prove it handles better for your business.
LiteLLM is an open-source Python SDK and LLM gateway. It gives teams one interface for more than 100 model providers and adds tools such as authentication, logging, budgets, load balancing, retries and fallbacks. It is used when a team wants one control point for a broad model stack.
It can be used as both. The Python SDK standardises calls inside an application, while LiteLLM Proxy can run as a central AI gateway in front of multiple model providers. Your team still chooses, configures and operates those routes.
Yes. Keep LiteLLM for the model traffic, controls and provider fallbacks your platform team already manages. Send a defined content, catalogue, localization or similar workload to Omev after it passes your acceptance test. The two routes can remain separate.
LiteLLM states that its open-source gateway is free to self-host. That means no gateway licence fee, not zero total cost. Add the underlying model bills, hosting, databases, monitoring, upgrades and operational time. LiteLLM Enterprise uses quoted annual pricing based on request capacity, deployment architecture and support needs.
There is no honest single-number comparison. LiteLLM passes calls to providers whose rates you choose and adds the cost of operating the gateway. Omev includes model inference in its published usage rates. Compare the total cost of one accepted output, including retries and review time.
No. Omev is not a catalogue of third-party models. Its public text API exposes Omev Lite and Omev Pro. Keep LiteLLM when choosing named third-party models is a requirement.
With LiteLLM, your team configures providers, deployments, retries and fallbacks. With Omev, the service handles its own models for the workload you send. Keep a fallback in your application when the business process requires one.
Choose one repeated task, agree the approval rules and run a representative sample through Omev while the current LiteLLM route stays live. Compare accepted outputs, total cost and editor time. Move only the task that earns the change.
$5 of credit for 10 days, with no card required. Use it on a representative workload and keep the current stack connected while you compare the results.
Bring a repeated task, real samples and the rules your team already uses to approve the work. Move nothing until the output and economics make sense.
Benchmark one workload →