Our first option to test for content
Omev AI
Evaluate Lite for concise, repeatable outputs and Pro for longer drafts or briefs. Give the model source facts, a clear format and acceptance rules.
API pricing & content workload comparison
Test Omev AI on the drafts, metadata and rewrites your team produces repeatedly. Compare the bill with Claude standard, Batch and cached usage, then choose using the output your team approves.
$5 free credit · 10 days · no card

By Di Reshtei, Co-founder of OmevAI · X
Rates checked
This compares paid API usage. Claude app subscriptions are separate. Omev AI publishes this guide; each provider still needs to earn its place on your workload.
Our first option to test for content
Evaluate Lite for concise, repeatable outputs and Pro for longer drafts or briefs. Give the model source facts, a clear format and acceptance rules.
Keep what your application relies on
Keep Claude for tasks where its tested output or native features matter. Include the discounts your application actually uses when comparing the bill.
Selected standard text rates in USD per million tokens, checked September 14, 2026. Claude rows use the direct API's default global pricing. Cached input, Batch and non-token charges are separate.
| Model | Input / 1M | Output / 1M |
|---|---|---|
| OmevAI Lite | $0.15 | $1.25 |
| OmevAI Pro | $0.625 | $5 |
| Claude Sonnet 5.5 ↗ | $2 | $10 |
| Claude Haiku 5.5 ↗ | $0.1 | $0.5 |
| Claude Sonnet 5 · legacy ↗ | $2 | $10 |
| Claude Haiku 4.5 · legacy ↗ | $1 | $5 |
| Claude Sonnet 4.6 · legacy ↗ | $3 | $15 |
These are price comparisons, not evidence of equivalent quality. Tools, inference geography, cloud-provider terms and negotiated discounts can change the total. Check Anthropic's full rate card ↗
Assume 10,000 drafts in a month, each using 3,000 input and 2,000 output tokens: 30,000,000 input and 20,000,000 output tokens in total.
$118.75
Published standard rates
$260
Standard API rates
$130
Asynchronous, discounted rates
This is a worked token budget, not a measured production bill. The same text can produce different token counts across models; drafting length, retries and review also vary. Replace these assumptions with billed usage from your own pilot.
Anthropic's Message Batches API halves input and output token rates for supported requests. For Sonnet 5, that gives $1 input and $5 output per million tokens, taking the illustrated bill from $260 to $130.
Batch work is asynchronous. Processing can take up to 24 hours, and requests can expire. It can suit a scheduled publishing queue; verify timing before using it for a draft someone is waiting to receive.
At this volume, Omev Pro costs $11.25 less than Sonnet 5 Batch. Even a small difference in review effort could outweigh it. Test both output and total cost.
Repeated source material changes the economics. For Haiku 4.5, a 5-minute cache write costs $1.25 per million tokens and a cache hit costs $0.1; fresh input and output retain their standard rates. A cheap cache read is only one part of the bill.
Assume 100 extraction calls over the same 100,000-token source: one cache write, 99 successful hits, plus 1,000 fresh input and 100 output tokens per call. Keep the prefix unchanged and reuse it before expiry. The hits are an assumption to verify in your usage logs.
Omev Lite, standard input
$1.5275
Claude Haiku 4.5, cached input
$1.265
The comparison uses identical token volumes and includes the write premium. The linked calculator uses an average Claude input rate based on this mix of writes, reads and fresh tokens. It does not simulate individual cache hits. No Batch discount is applied here.
A lower token price helps when the output meets the brief. Use the same source facts and review rules, then compare approved results, retries and editing time.
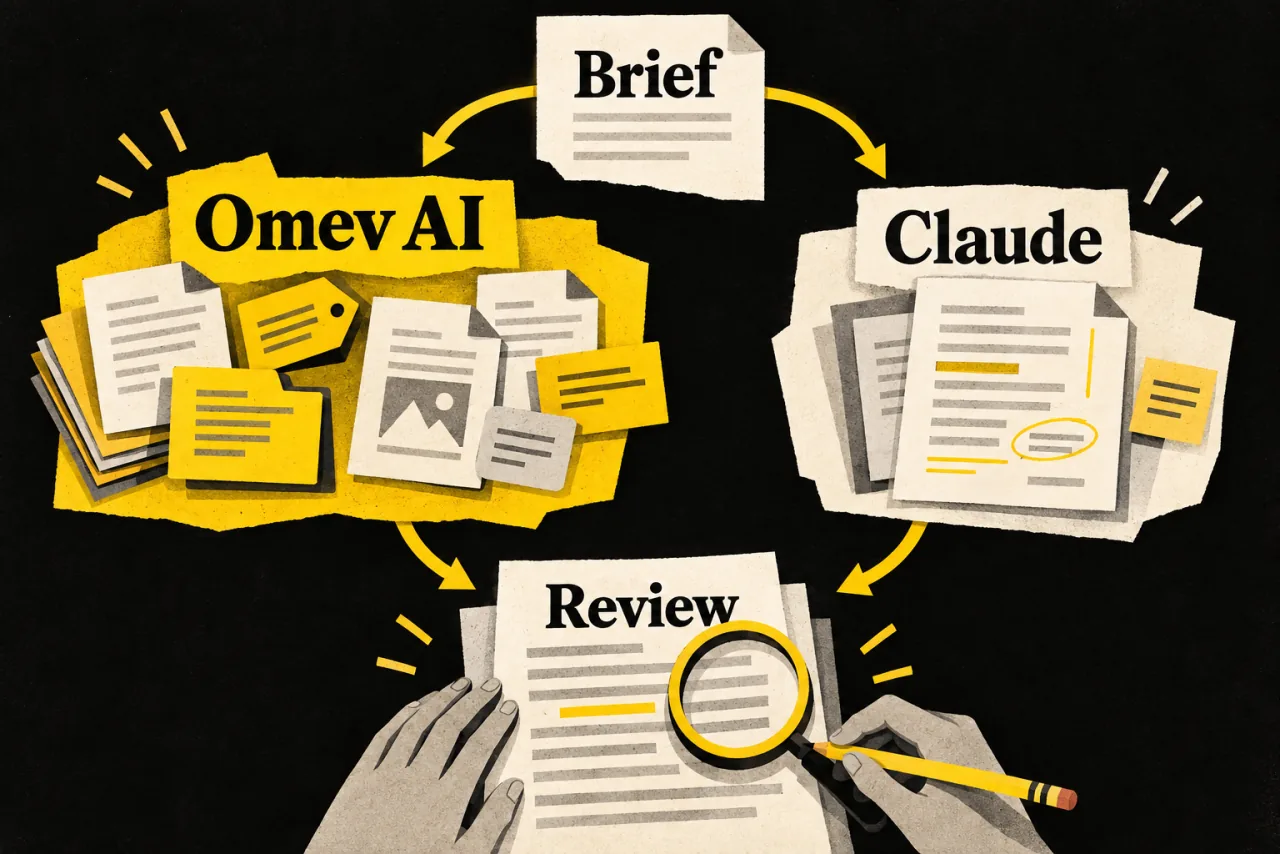
Try metadata, product descriptions, constrained rewrites or briefs with explicit source facts. Evaluate Lite or Pro according to the task; keep the existing route until the results pass review.
Retain workloads that depend on Claude-specific features, established output behavior or effective rates that already work for you. Compare approved-output cost, including API charges and editorial effort.
For migration, map native Claude Messages calls to Omev's supported Chat Completions interface. Check response content, streaming, usage and failure handling. An endpoint change alone does not recreate an Anthropic SDK integration.
Check content terms before uploading briefs. Omev uses inputs and outputs for training and improvement, with no opt-out; self-service content must not contain personal data. Read Omev's customer-content terms.
This compares usage-based API token charges. Claude app subscriptions are separate products and are not the rates used in these examples. Use your API invoice and the model actually serving your workload.
For the illustrated 10,000-draft volume, Omev Pro costs $118.75, Sonnet 5 standard costs $260, and Sonnet 5 Batch costs $130. The cache-heavy Haiku example goes the other way. Your model, input mix, cache reuse and review time determine the useful comparison.
Yes. The Message Batches API discounts input and output token rates by 50% for supported asynchronous requests. Processing can take up to 24 hours and requests can expire. Compare that delivery mode with the timing your workflow needs; use the Batch example link to edit the same volumes in the calculator.
Count cache writes, successful reads, uncached input and output separately. A 5-minute write carries a premium, so a cheap read rate alone understates the total. The worked Haiku example includes one write and 99 hits, then converts those input charges into a weighted rate for the calculator.
They are candidates for tasks you can evaluate, not established quality equivalents. Start with Lite for short, repeatable outputs and Pro for longer drafts or briefs with more constraints. Keep Claude where its results, tools or model-specific behavior are required.
Native Claude Messages calls do not transfer unchanged to Omev's OpenAI-compatible Chat Completions interface. Map the request, response content, streaming, usage and errors. Claude-specific features and output controls need their own assessment. The linked migration guide covers what to check before moving a task.
Signup includes $5 of credit for 10 days with no card required. Use it for a representative set of text briefs, compare accepted results and review effort, then decide whether to move that part of the workload.
Bring a real brief and your quality bar. Use the trial to compare what your team can approve, then price the volume you plan to move.
Start your Omev AI test →